
About Me
Who I amI'm Claudio, a mathematician who moved into data science and never looked back. I'm based in Santiago, Chile, originally from Padre Las Casas, La Araucanía — a region I still go back to regularly to mentor and give talks at my alma mater, Universidad de La Frontera.
Data Science
platforms
since 2013
projects shipped
My philosophy is simple: elegant solutions over complicated ones. I've seen too many pipelines fail under their own weight. I believe the best models are the ones that are maintainable, explainable, and actually ship.
What I doCurrently working as a Data Engineer at ClaroVTR, focused on monitoring and maintaining automated data pipelines and auditing Data Engineering and Data Science projects for quality and best practice. Before that I spent close to three years as Data Science Tech Lead, leading and mentoring a team of data scientists and owning technical roadmap and architecture decisions, and four years as a Senior Data Scientist building production churn models, clustering algorithms, and feature-engineering frameworks in PySpark on AWS. I also spent a few months as an AI Specialist at Xinergy Procurement Consulting, building LLM-based classification and RAG systems with Gemini and LangChain.
I got my degree in Ingeniería Civil Matemática from Universidad de La Frontera, where I focused on parallel programming, numerical methods, and mathematical modelling — skills that ended up translating directly into Big Data work.
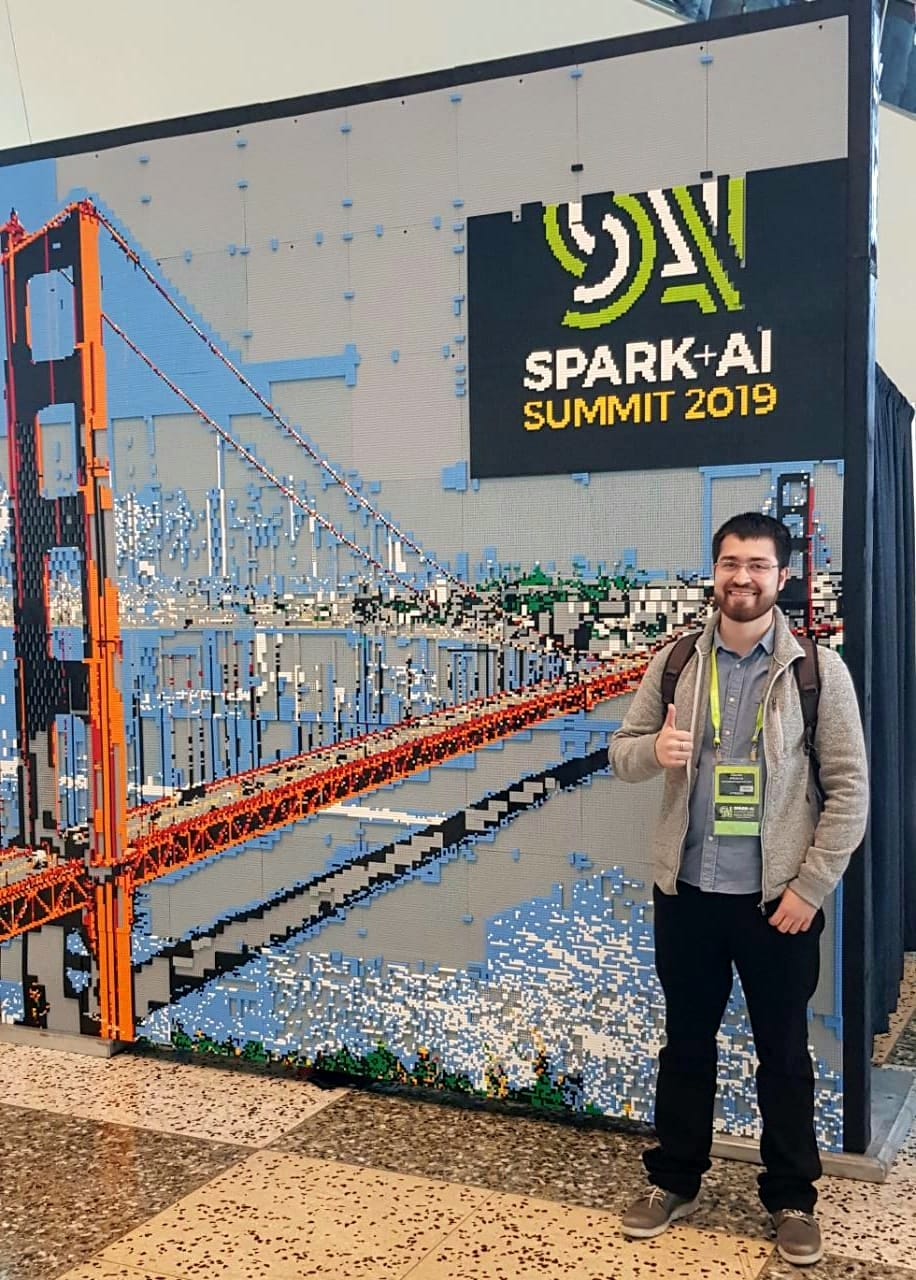
At Spark Summit, San Francisco (2019).
Outside of workOutside of my day job I build small software projects end-to-end — from a 3D globe renderer that turns a travel itinerary into an Instagram Stories video, to CLI tools and automations that fix a specific annoyance in my own life. A few of the ones I'm most proud of are on the homepage — click a project node there for a summary — and linked from my GitHub.